Что это значит, когда загрузка процессора 0% в Диспетчере задач Windows?
Я не знаю, есть ли инструкция, которая могла бы сделать процессор простоя. И я также замечаю, что есть Процесс Простоя Системы, которые используют 99% ЦП, когда ЦП показывает 0%. Что это за процесс простоя системы? Если он использует 99% процессора, почему температура процессора ниже, чем у другого процесса, занимающего 99% процессора?
позвольте мне поставить его немного дальше, как рассчитывается процент использования процессора?
может быть, это немой вопрос. Надеюсь, выродки здесь не будут чувствовать себя утомительными. ��
19.01.2023 9:30 2746
3 ответа
процесс бездействия системы — это программа, которая представляет собой бесконечный цикл бездействующих команд с приоритетом ниже минимально возможного приоритета.
ваш процессор никогда не может» остановиться», так сказать, однако обычно есть команда простоя (или что-то подобное), которая может быть запущена на процессоре.
команда холостого хода — это просто команда, которая предназначена для использования наименьшего количества каналов, возможных на вашем процессоре, тем самым сохраняя его температуру как можно ниже.
то, что сказал stargazer, плюс использование процессора рассчитывается как процент емкости (расчеты в секунду ака провалы), что каждый процесс использует.
Это означает, что все процессы замерли в ожидании. они «заблокированы» на таких вещах, как пользовательский ввод, сетевая карта, данные жесткого диска или даже оперативная память.
в основном это означает, что потоки все ждут операционной системы, чтобы позволить им работать снова. он делает это, используя то, что называется прерыванием. Некоторые interupts приурочены, именно поэтому ваши часы меняется каждую секунду или минуту, но ваш компьютер не должен отслеживать его 100% времени.
Cpu0 architecture and LLVM structure
Before you begin this tutorial, you should know that you can always try to develop your own backend by porting code from existing backends. The majority of the code you will want to investigate can be found in the /lib/Target directory of your root LLVM installation. As most major RISC instruction sets have some similarities, this may be the avenue you might try if you are an experienced programmer and knowledgable of compiler backends.
On the other hand, there is a steep learning curve and you may easily get stuck debugging your new backend. You can easily spend a lot of time tracing which methods are callbacks of some function, or which are calling some overridden method deep in the LLVM codebase — and with a codebase as large as LLVM, all of this can easily become difficult to keep track of. This tutorial will help you work through this process while learning the fundamentals of LLVM backend design. It will show you what is necessary to get your first backend functional and complete, and it should help you understand how to debug your backend when it produces incorrect machine code using output provided by the compiler.
This chapter details the Cpu0 instruction set and the structure of LLVM. The LLVM structure information is adapted from Chris Lattner’s LLVM chapter of the Architecture of Open Source Applications book [ 10 ] . You can read the original article from the AOSA website if you prefer.
At the end of this Chapter, you will begin to create a new LLVM backend by writing register and instruction definitions in the Target Description files which will be used in next chapter.
Finally, there are compiler knowledge like DAG (Directed-Acyclic-Graph) and instruction selection needed in llvm backend design, and they are explained here.
Cpu0 Processor Architecture Details
This section is based on materials available here [ 1 ] (Chinese) and here [ 2 ] (English). However, I changed some ISA from original Cpu0 for designing a simple integer operational CPU and llvm backend. This is my intention for writing this book that I want to know what a simple and robotic CPU ISA and llvm backend can be.
Brief introduction
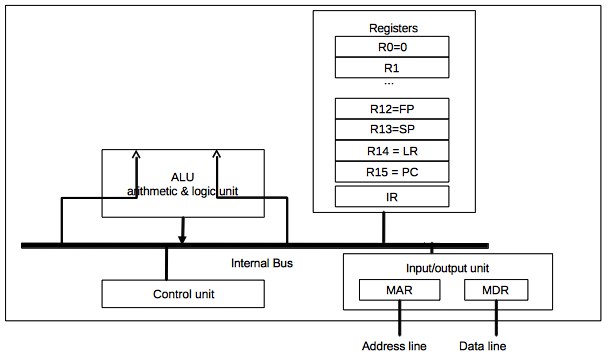
Cpu0 is a 32-bit architecture. It has 16 general purpose registers (R0, …, R15), co-processor registers (like Mips), and other special registers. Its structure is illustrated in Fig. 3 below.
Fig. 3 Architectural block diagram of the Cpu0 processor 
The registers are used for the following purposes:
Table 2 Cpu0 general purpose registers (GPR) 
Constant register, value is 0
Global Pointer register (GP)
Frame Pointer register (FP)
Stack Pointer register (SP)
Link Register (LR)
Status Word Register (SW)
Program Counter (PC)
Error Program Counter (EPC)
Memory Address Register (MAR)
Memory Data Register (MDR)
High part of MULT result
Low part of MULT result
The Cpu0 Instruction Set
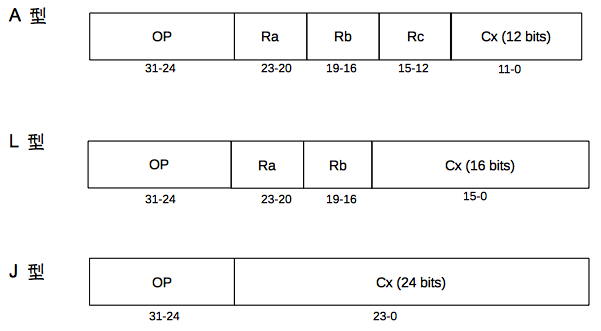
The Cpu0 instruction set can be divided into three types: L-type instructions, which are generally associated with memory operations, A-type instructions for arithmetic operations, and J-type instructions that are typically used when altering control flow (i.e. jumps). Fig. 4 illustrates how the bitfields are broken down for each type of instruction.
Fig. 4 Cpu0’s three instruction formats 
The Cpu0 has two ISA, the first ISA-I is cpu032I which hired CMP instruction from ARM; the second ISA-II is cpu032II which hired SLT instruction from Mips. The cpu032II include all cpu032I instruction set and add SLT, BEQ, …, instructions. The main purpose to add cpu032II is for instruction set design explanation. As you will see in later chapter (chapter Control flow statements), the SLT instruction will has better performance than CMP old style instruction. The following table details the cpu032I instruction set:
First column F.: meaning Format.
Load byte unsigned
Load half word unsigned
Store half word
Count Leading Zero
Ra <= bits of leading zero on Rb
Count Leading One
Ra <= bits of leading one on Rb
Bitwise exclusive or
Bitwise boolean nor
if SW(==), PC <= PC + Cx
Jump if not equal (!=)
if SW(!=), PC <= PC + Cx
Jump if less than (<)
if SW(<), PC <= PC + Cx
Jump if greater than (>)
if SW(>), PC <= PC + Cx
Jump if less than or equals (<=)
if SW(<=), PC <= PC + Cx
Jump if greater than or equals (>=)
if SW(>=), PC <= PC + Cx
Branch and link
LR <= PC; PC <= PC + Cx
Jump to subroutine
LR <= PC; PC <= PC + Cx
Return from subroutine
Multiply for 64 bits result
MULT for unsigned 64 bits
Move C0R to GPR
Move GPR to C0R
Move C0R to C0R
The following table details the cpu032II instruction set added:
Table 6 cpu032II Instruction Set 
Branch if equal
if (Ra==Rb), PC <= PC + Cx
Branch if not equal
if (Ra!=Rb), PC <= PC + Cx
Cpu0 unsigned instructions
Like Mips, except DIVU, the mathematic unsigned instructions such as ADDu and SUBu, are instructions of no overflow exception. The ADDu and SUBu handle both signed and unsigned integers well. For example, (ADDu 1, -2) is -1; (ADDu 0x01, 0xfffffffe) is 0xffffffff = (4G — 1). If you treat the result is negative then it is -1. On the other hand, it’s (+4G — 1) if you treat the result is positive.
Why not using ADD instead of SUB?
From text book of computer introduction, we know SUB can be replaced by ADD as follows,
Since Mips uses 32 bits to represent int type of C language, if B is the value of -2G, then
But the problem is value -2G can be represented in 32 bits machine while 2G cannot, since the range of 2’s complement representation for 32 bits is (-2G .. 2G-1). The 2’s complement reprentation has the merit of fast computation in circuits design, it is widely used in real CPU implementation. That’s why almost every CPU create SUB instruction, rather than using ADD instead of.
The Status Register
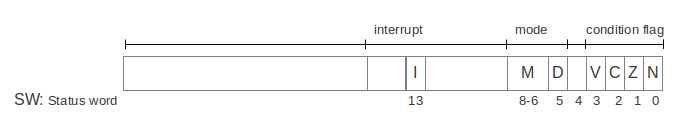
The Cpu0 status word register (SW) contains the state of the Negative (N), Zero (Z), Carry (C), Overflow (V), Debug (D), Mode (M), and Interrupt (I) flags. The bit layout of the SW register is shown in Fig. 5 below.
Fig. 5 Cpu0 status word (SW) register 
When a CMP Ra, Rb instruction executes, the condition flags will change. For example:
If Ra > Rb, then N = 0, Z = 0
If Ra < Rb, then N = 1, Z = 0
If Ra = Rb, then N = 0, Z = 1
The direction (i.e. taken/not taken) of the conditional jump instructions JGT, JLT, JGE, JLE, JEQ, JNE is determined by the N and Z flags in the SW register.
Cpu0’s Stages of Instruction Execution
The Cpu0 architecture has a five-stage pipeline. The stages are instruction fetch (IF), instruction decode (ID), execute (EX), memory access (MEM) and write backe (WB). Here is a description of what happens in the processor for each stage:
Instruction fetch (IF)
The Cpu0 fetches the instruction pointed to by the Program Counter (PC) into the Instruction Register (IR): IR = [PC].
The PC is then updated to point to the next instruction: PC = PC + 4.
Instruction decode (ID)
The control unit decodes the instruction stored in IR, which routes necessary data stored in registers to the ALU, and sets the ALU’s operation mode based on the current instruction’s opcode.
The ALU executes the operation designated by the control unit upon data in registers. Except load and store instructions, the result is stored in the destination register after the ALU is done.
Memory access (MEM)
Read data from data cache to pipeline register MEM/WB if it is load instruction; write data from register to data cache if it is strore instruction.
Move data from pipeline register MEM/WB to Register if it is load instruction.
Cpu0’s Interrupt Vector
LLVM Structure
This section introduces the compiler data structure, algorithm and mechanism that llvm uses.
Three-phase design
The text in this and the following sub-section comes from the AOSA chapter on LLVM written by Chris Lattner [ 10 ] .
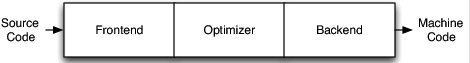
The most popular design for a traditional static compiler (like most C compilers) is the three phase design whose major components are the front end, the optimizer and the back end, as seen in Fig. 6 . The front end parses source code, checking it for errors, and builds a language-specific Abstract Syntax Tree (AST) to represent the input code. The AST is optionally converted to a new representation for optimization, and the optimizer and back end are run on the code.
Fig. 6 Three Major Components of a Three Phase Compiler 
The optimizer is responsible for doing a broad variety of transformations to try to improve the code’s running time, such as eliminating redundant computations, and is usually more or less independent of language and target. The back end (also known as the code generator) then maps the code onto the target instruction set. In addition to making correct code, it is responsible for generating good code that takes advantage of unusual features of the supported architecture. Common parts of a compiler back end include instruction selection, register allocation, and instruction scheduling.
This model applies equally well to interpreters and JIT compilers. The Java Virtual Machine (JVM) is also an implementation of this model, which uses Java bytecode as the interface between the front end and optimizer.
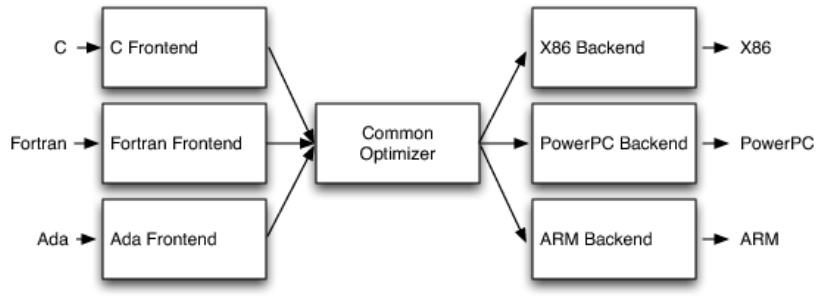
The most important win of this classical design comes when a compiler decides to support multiple source languages or target architectures. If the compiler uses a common code representation in its optimizer, then a front end can be written for any language that can compile to it, and a back end can be written for any target that can compile from it, as shown in Fig. 7 .
Fig. 7 Retargetablity 
With this design, porting the compiler to support a new source language (e.g., Algol or BASIC) requires implementing a new front end, but the existing optimizer and back end can be reused. If these parts weren’t separated, implementing a new source language would require starting over from scratch, so supporting N targets and M source languages would need N*M compilers.
Another advantage of the three-phase design (which follows directly from retargetability) is that the compiler serves a broader set of programmers than it would if it only supported one source language and one target. For an open source project, this means that there is a larger community of potential contributors to draw from, which naturally leads to more enhancements and improvements to the compiler. This is the reason why open source compilers that serve many communities (like GCC) tend to generate better optimized machine code than narrower compilers like FreePASCAL. This isn’t the case for proprietary compilers, whose quality is directly related to the project’s budget. For example, the Intel ICC Compiler is widely known for the quality of code it generates, even though it serves a narrow audience.
A final major win of the three-phase design is that the skills required to implement a front end are different than those required for the optimizer and back end. Separating these makes it easier for a “front-end person” to enhance and maintain their part of the compiler. While this is a social issue, not a technical one, it matters a lot in practice, particularly for open source projects that want to reduce the barrier to contributing as much as possible.
The most important aspect of its design is the LLVM Intermediate Representation (IR), which is the form it uses to represent code in the compiler. LLVM IR is designed to host mid-level analyses and transformations that you find in the optimizer chapter of a compiler. It was designed with many specific goals in mind, including supporting lightweight runtime optimizations, cross-function/interprocedural optimizations, whole program analysis, and aggressive restructuring transformations, etc. The most important aspect of it, though, is that it is itself defined as a first class language with well-defined semantics. To make this concrete, here is a simple example of a .ll file:
As you can see from this example, LLVM IR is a low-level RISC-like virtual instruction set. Like a real RISC instruction set, it supports linear sequences of simple instructions like add, subtract, compare, and branch. These instructions are in three address form, which means that they take some number of inputs and produce a result in a different register. LLVM IR supports labels and generally looks like a weird form of assembly language.
Unlike most RISC instruction sets, LLVM is strongly typed with a simple type system (e.g., i32 is a 32-bit integer, i32** is a pointer to pointer to 32-bit integer) and some details of the machine are abstracted away. For example, the calling convention is abstracted through call and ret instructions and explicit arguments. Another significant difference from machine code is that the LLVM IR doesn’t use a fixed set of named registers, it uses an infinite set of temporaries named with a % character.
Beyond being implemented as a language, LLVM IR is actually defined in three isomorphic forms: the textual format above, an in-memory data structure inspected and modified by optimizations themselves, and an efficient and dense on-disk binary “bitcode” format. The LLVM Project also provides tools to convert the on-disk format from text to binary: llvm-as assembles the textual .ll file into a .bc file containing the bitcode goop and llvm-dis turns a .bc file into a .ll file.
The intermediate representation of a compiler is interesting because it can be a “perfect world” for the compiler optimizer: unlike the front end and back end of the compiler, the optimizer isn’t constrained by either a specific source language or a specific target machine. On the other hand, it has to serve both well: it has to be designed to be easy for a front end to generate and be expressive enough to allow important optimizations to be performed for real targets.
LLVM’s Target Description Files: .td
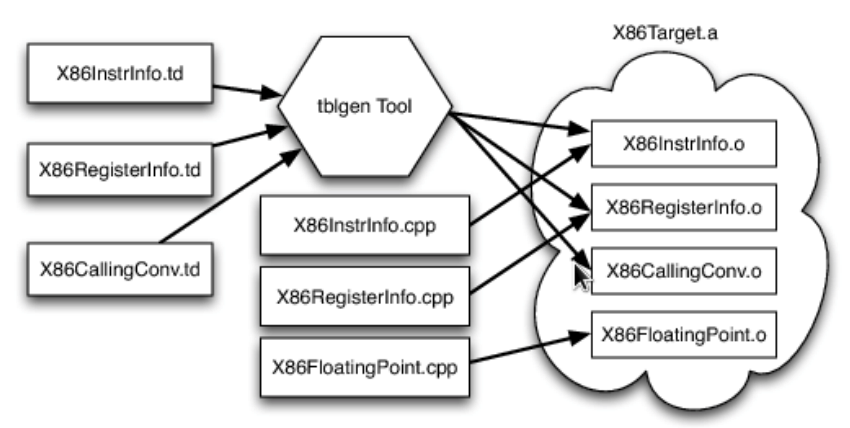
The “mix and match” approach allows target authors to choose what makes sense for their architecture and permits a large amount of code reuse across different targets. This brings up another challenge: each shared component needs to be able to reason about target specific properties in a generic way. For example, a shared register allocator needs to know the register file of each target and the constraints that exist between instructions and their register operands. LLVM’s solution to this is for each target to provide a target description in a declarative domain-specific language (a set of .td files) processed by the tblgen tool. The (simplified) build process for the x86 target is shown in Fig. 8 .
Fig. 8 Simplified x86 Target Definition 
The different subsystems supported by the .td files allow target authors to build up the different pieces of their target. For example, the x86 back end defines a register class that holds all of its 32-bit registers named “GR32” (in the .td files, target specific definitions are all caps) like this:
The language used in .td files are Target(Hardware) Description Language that let llvm backend compiler engineers to define the transformation for llvm IR and the machine instructions of their CPUs. In frontend, compiler development tools provide the “Parser Generator” for compiler development; in backend, they provide the “Machine Code Generator” for development, as the following figures.
Fig. 9 tricore_llvm.pdf: Code generation sequence. On the path from LLVM code to assembly code, numerous passes are run through and several data structures are used to represent the intermediate results. 
LLVM is a Static Single Assignment (SSA) based representation. LLVM provides an infinite virtual registers which can hold values of primitive type (integral, floating point, or pointer values). So, every operand can be saved in different virtual register in llvm SSA representation. Comment is “;” in llvm representation. Following is the llvm SSA instructions.
Загрузка ЦП: 0%
Вообщем, как только захожу в игры, прямо в меню начинаются дикие фризы и с каждым разом все дольше в конце концов игра вообще навсегда зависает, при этом всем нагрузка на ЦП: 0%, изредка выскакивает BSOD 7a ntfs.sys, но HDD куплен недавно и до этого все прекрасно было. Еще когда все работает комп издает звук треска, а как фризанет — компьютер затихает, потом снова трещит. Самое странное, что все это происходит во всех играх, кроме Rainbow Six: Siege, там вообще все прекрасно.
CPU: AMD Phenom X6 1055t 2.8 Ghz RAM: 4096 Mb GPU: GTX 750 Ti 2048 Mb HDD: Western Digital Caviar Black (WD5001aals-00l3b2) 500 Gb
Cpu 0 что это
Вообщем, как только захожу в игры, прямо в меню начинаются дикие фризы и с каждым разом все дольше в конце концов игра вообще навсегда зависает, при этом всем нагрузка на ЦП: 0%, изредка выскакивает BSOD 7a ntfs.sys, но HDD куплен недавно и до этого все прекрасно было. Еще когда все работает комп издает звук треска, а как фризанет — компьютер затихает, потом снова трещит. Самое странное, что все это происходит во всех играх, кроме Rainbow Six: Siege, там вообще все прекрасно.
CPU: AMD Phenom X6 1055t 2.8 Ghz RAM: 4096 Mb GPU: GTX 750 Ti 2048 Mb HDD: Western Digital Caviar Black (WD5001aals-00l3b2) 500 Gb
What does CPU#0 stuck mean?
I tried loading a live disk of Ubuntu 12.04 on my XP computer and it keeps repeating «CPU#0 stuck for x seconds.» Can someone please help me?
1 Answer 1
The Linux kernel has a process which monitors each CPU on the system.
There are special interrupt(s) in the kernel. This interrupt(s) function calls a soft-lockup counter, it will compare the current time stamp with the specific kernel CPU data structure time information. If it looks like the current time stamp is greater than the defined threshold (in seconds) later as compared to the stored time stamp, it is assumed that the monitoring process or watchdog thread(s) have not executed in a respectable amount of time.
Why or how can a CPU soft lock occur? How can a CPU get locked if the kernel is carefully scheduling CPU access? Basically any poorly written code that loops a lot or infinitely, would own a CPU and get some priority. It can be a programming problem or 3rd party software.
Locking issues in drivers. Even kernel bugs in important drivers or the scheduler. A scheduler could tell schedule a driver routine to run and if that driver has problems and doesn’t check on it, that driver routine could own or hog that CPU for a longtime. By definition as described above, the watchdog would catch this and issue a soft lockup alert.
Soft lockups mostly hang a CPU and possibly your system temporarily.
A kernel update may fix the problem. To update the kernel, just press Ctrl + Alt + T on your keyboard to open Terminal. When it opens, run the command(s) below: